My AI finance advisor invented numbers on real bank data, and instructions didn't stop it. A check in code did, and the same idea cut AI cost by ~80%.
The advisor said things that couldn't be true
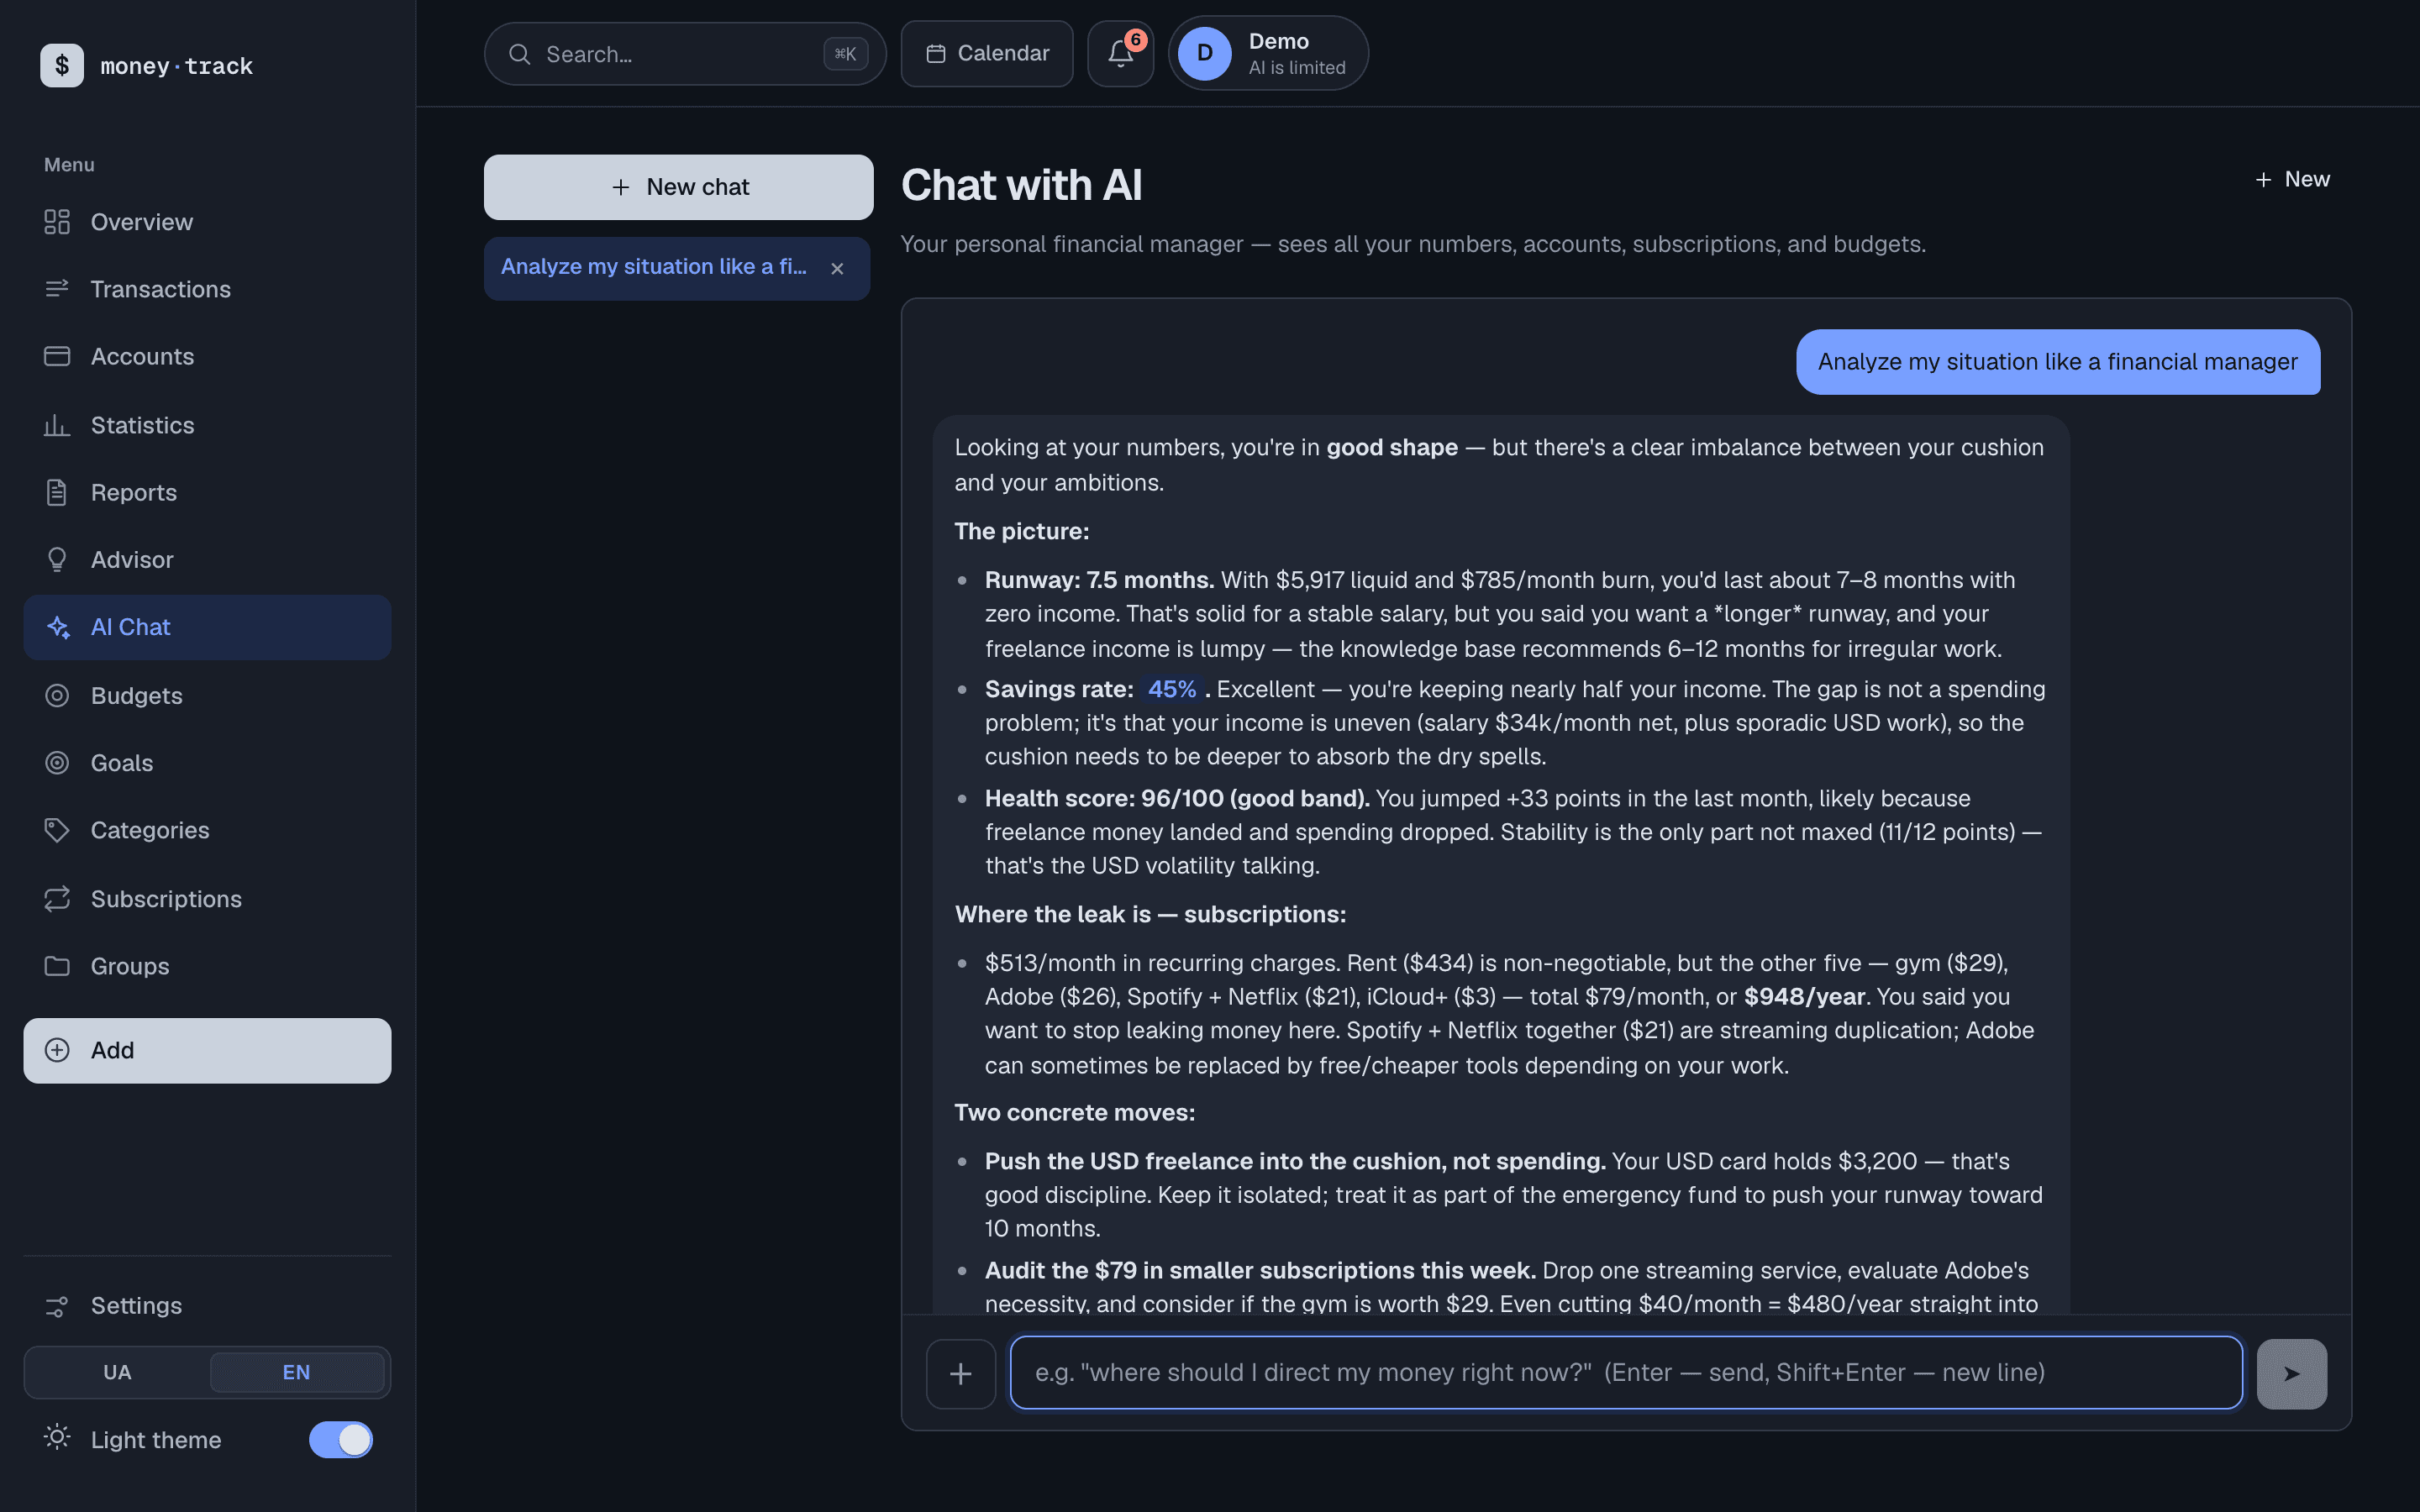
My finance app's AI told me things I knew were wrong. Spending far higher than it really was. A charge counted in this month's numbers that hadn't happened in months.
Money Track is my personal finance app. It syncs bank statements, sorts spending into categories and has an AI advisor you can ask things like "can I afford this?" On sample data it looked fine. On my real data it started making numbers up.
In a finance app, a confidently wrong number is worse than no answer. You act on it.
Telling the model didn't work
My first reaction was the usual one: tell the model more clearly. The part of the app that writes notifications already had that instruction. It was told to only repeat figures the app had already calculated, never to work out its own.
That changed how I thought about the problem. The goal was never a model that is careful. It was making sure a wrong number can't reach the screen quietly.
An instruction to the model is a request. A check in code is a guarantee.
Every number comes from SQL
So I took the arithmetic away from the model completely.
- Every figure is computed in SQL, by the same queries the app's screens use. The chat and the dashboard can't disagree, because they read one source.
- The model gets that snapshot plus read-only tools to look things up. It explains and phrases. It never adds anything up.
- Before an answer is shown, a check compares every sum in it with the numbers the model was given. A figure that isn't there gets dropped.
The check is small. It finds every number in the text and looks for it in the data, with a 1% tolerance for rounding. Anything under 100 is skipped, because counts and percentages are not sums of money.
export function numbersAreGrounded(text: string, known: Set<number>): boolean {
// spaces inside a number are thousands separators ("3 354")
const found = text.match(/\d[\d\s]*(?:[.,]\d+)?/g) ?? [];
for (const raw of found) {
const n = Math.abs(Number(raw.replace(/\s/g, "").replace(",", ".")));
if (!Number.isFinite(n) || n < 100) continue;
let ok = false;
for (const k of known) {
if (Math.abs(n - k) <= Math.max(1, k * 0.01)) { ok = true; break; }
}
if (!ok) return false;
}
return true;
}
The same kind of check covers dates and day counts. If the database didn't produce a number, you don't see it.
The check can't fix bad data
The check has a limit, and I hit it a few weeks later.
The app told me that English lessons were shortening my runway, at about $31 a month. I had cancelled that subscription in June. The number was real: the data showed each merchant's spending over the last 90 days divided by three, and the last charges were in June. The model was warned in the prompt not to rely on that figure, and relied on it anyway. The check couldn't object, because the number was genuinely in the data.
I fixed it by removing the number, not by adding more warnings. A merchant with no charges for 45 days now comes with "stopped" and the days since the last payment, not a monthly figure. The model can't misuse a number it never gets.
So the check guards what the model writes. You still have to check what you give it.
Rules first, a model only where needed
The same idea works for sorting transactions into categories, which is where most of the AI cost goes.
- Plain rules run first: merchants you've already filed, known subscriptions, what most users filed a merchant under, the bank's merchant category codes.
- Only the rows the rules can't settle go to a model.
- Recently I added Jev, a small judgment model from TypeSafe, in front of Claude Haiku. Jev files a row itself only when it's at least 80% sure. Everything else goes to Haiku.
The 80% line wasn't a guess. In the eval, every answer Jev gave at 0.8 or above was right, and every miss sat below 0.75. That covers 85% of the rows that reach a model.
The cascade gets about 97% of categories right, the same as Haiku alone, at about a fifth of the cost. It's also faster: on the same eval run Jev took 8 seconds where Haiku took 42.
Measure on cases you never tuned on
The most useful thing I built for the AI wasn't a prompt. It was an eval: npm run eval runs the real categorisation code over 168 raw bank descriptions and reports accuracy and cost together. Before it, every prompt change was judged by reading a few rows and forming an impression.
It paid off twice.
A score of 98.9% that meant nothing
I tuned Jev on that dataset and it scored 98.9%. Then I wrote 36 new merchants it had never seen and ran it again: 72%.
The cause was mine. Jev's instructions were a shorter copy of the category guide I'd written by hand, and the copy had lost the lists of brands. Two definitions of the same thing had drifted apart. Now both models read one guide, and those 36 merchants stay as a test I never tune on. Haiku gets 35 of them right, and the whole run costs $0.03.
A cache that was never on
The eval also showed that prompt caching had never worked for categorisation. The cached guide was 18 tokens short of the minimum Haiku will cache. The API doesn't fail or warn when that happens. It just bills the full prompt every time, and a cache that never engages looks exactly like one that does.
I padded the guide with real guidance, not filler, so accuracy went up too:
A test now fails the build if the guide gets too short again.
You can try it yourself: the Money Track demo creates a private sandbox with six months of sample data that resets after 24 hours. The code is open source, and the case study goes deeper into the architecture.
Does your model invent numbers too? Tell me what you're building, on Telegram or by email.
Vitaliy Hrytsenko, full-stack developer building AI products. Solo, from decision to production.
Telegram ↗X ↗